01.A / CACHE
Keep hot data close.
Store a value. Give it a TTL. Keep frequently used data handy, with bounded memory and eviction.
report:42readyTTL 60sYour cache, background jobs, and event streams.
Together in one small C server.
For the SaaS you're building, and the infrastructure
you'd rather keep simple.
python3 -m pip install --pre kuttidbfrom kuttidb import KuttiDBClient
with KuttiDBClient(port=7379) as db:
db.put("report:42", b"ready", ttl=60)
status = db.get("report:42")
print(status)
# b'ready'Install the Python client and connect to a server on port 7379.
The everyday building blocks of a SaaS,
with one server to configure and operate.
Store a value. Give it a TTL. Keep frequently used data handy, with bounded memory and eviction.
report:42readyTTL 60sHand a job to a worker. Acknowledge it when it's done. Retry unfinished work and route failures to a dead-letter queue.
reports3 readyACK + retryAppend events to a partitioned log. Save your place with offsets and replay the history within your retention window.
report.readyoffset 42replayableCache a status. Process a job. Append an event.
Then crash the process and see what survives.
One report worker. All three engines.
A job is still waiting for an ACK.
Reopen the same data directory.
Recorded local run · about 9 seconds
Process-crash recovery on the same healthy disk. Cache uses --durability always. This demo does not test disk or machine loss.
When your cache and queue share an engine, the handoff can be one durable operation.
Read the commit contractdb.put_and_enqueue(…)After recovery, both sides exist.
Or neither does.
Atomic job completion commits durable state, the input ACK, and an optional next message together — with a receipt you can retry while it is retained. Deduplication covers the commit; processing itself remains at-least-once.
Explore job completion Opt-in with--job-completion and a durable queue.A self-hosted console for all three engines.
Inspect keys, browse jobs, and tail streams
through the authenticated Management API.
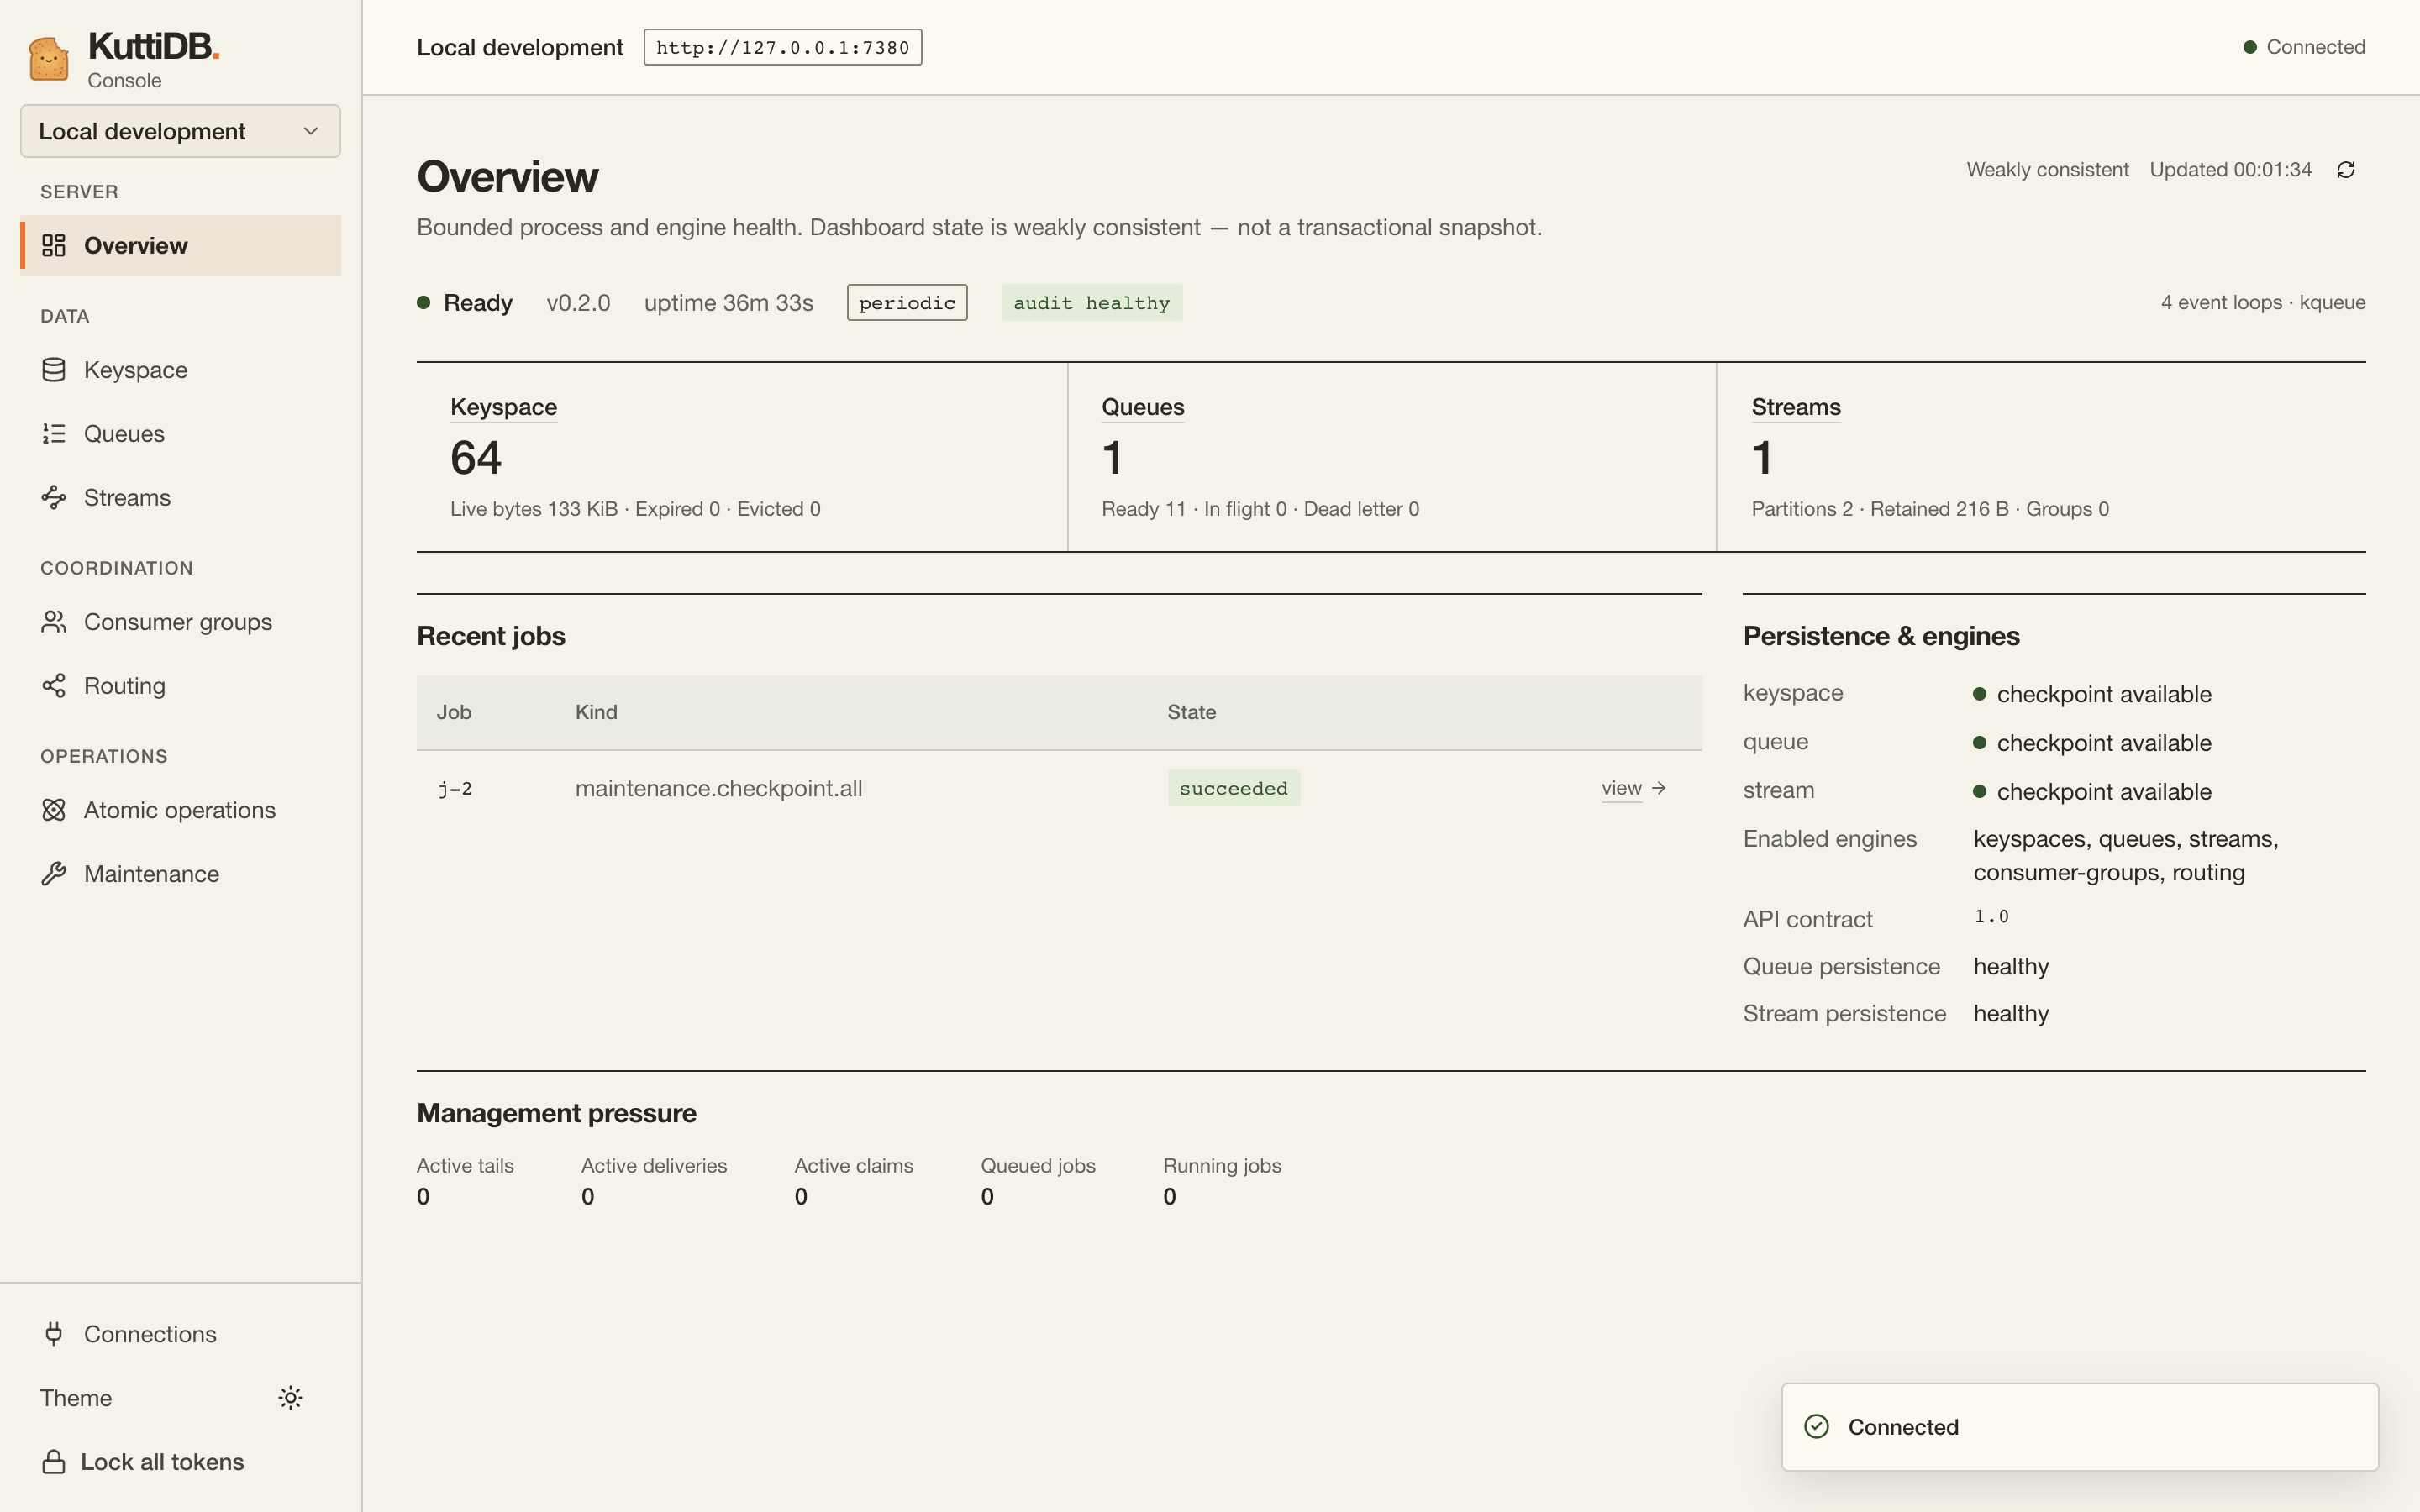
npx @kuttidb/management-uiNode 20+ · Opens at http://127.0.0.1:8080 and connects to your Management API.
View on npm ↗
Measured workloads. Public project activity.
Every figure comes with its context.
Three trials, medians. Batches of 256. Cache: 1-second durability window. Queue & stream: fsync-covered writes. One server; no replication.
Explore results & methodology ↗SDK downloads: npm & PyPI last 30 days; crates.io trailing month. These are activity counts, not unique users.
Explore project stats ↗For small and midsize SaaS teams who want
useful building blocks without a sprawling stack.
Applications running on one server that need caching, background jobs, and replayable events. Local clients can use shared memory; remote clients use KuttiDB's native protocol.
KuttiDB is beta software with no replication yet. Durable delivery is at-least-once. Cache entries can be evicted by policy. Evaluate these boundaries against your workload.
KuttiDB uses its own protocol and clients. Migrating from Redis, RabbitMQ, or Kafka requires application changes. It is designed around a smaller, single-server footprint.
Yes. KuttiDB is self-hosted and Apache-2.0 licensed. The management console is also self-hosted and runs separately against the authenticated Management API.
One command to take a bite.
No account. Your machine. Your data.
curl -fsSL https://kuttidb.com/demo.sh | bashmacOS or Linux · Python 3.10+ · curl
Temporary demo data. Cleans up after itself.
curl -fsSL https://kuttidb.com/install.sh | bashChecksum-verified releases for macOS and Linux.
Read the installer ↗